ai
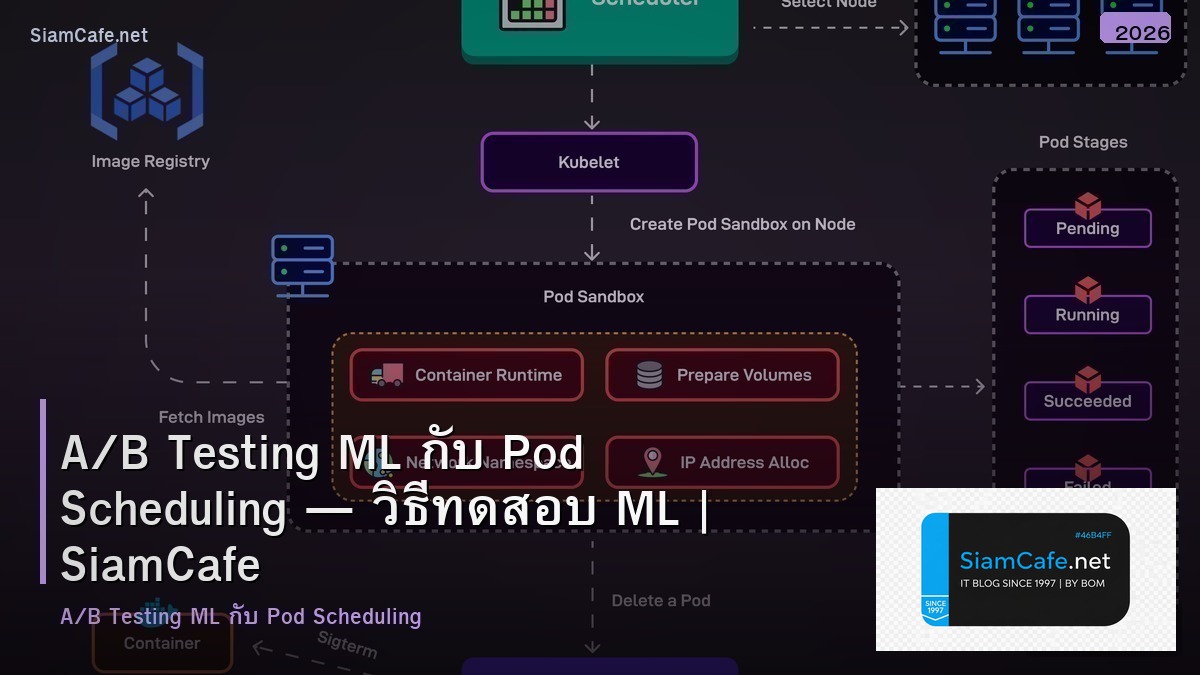
A/B Testing ML กับ Pod Scheduling — วิธีทดสอบ ML
A/B Testing สำหรับ ML Models
A/B Testing เป็นวิธีมาตรฐานในการเปรียบเทียบ ML Models ใน Production แทนที่จะ Deploy Model ใหม่ทดแทนทันที ส่ง Traffic บางส่วนไป Model ใหม่ (Challenger) และส่วนที่เหลือไป Model เดิม (Champion) แล้ววัดผลด้วย Business Metrics จริง
สำหรับ Kubernetes ต้องจัดการทั้ง Traffic Splitting (แบ่ง Traffic), Pod Scheduling (วาง Pod บน Node ที่เหมาะสม โดยเฉพาะ GPU Nodes) และ Monitoring (เก็บ Metrics เปรียบเทียบ) บทความนี้แสดงวิธีทำทั้งหมดพร้อม Config จริง
Kubernetes Config สำหรับ A/B Testing
# === Istio VirtualService — Traffic Splitting ===

apiVersion: networking.istio.io/v1beta1

kind: VirtualService

metadata:

  name: ml-model-ab-test

  namespace: ml-serving

spec:

  hosts:

    - ml-model.ml-serving.svc.cluster.local

  http:

    - match:

        - headers:

            x-model-version:

              exact: "challenger"

      route:

        - destination:

            host: ml-model-challenger

            port:

              number: 8080

    - route:

        - destination:

            host: ml-model-champion

            port:

              number: 8080

          weight: 90

        - destination:

            host: ml-model-challenger

            port:

              number: 8080

          weight: 10

---

# === Champion Model Deployment ===

apiVersion: apps/v1

kind: Deployment

metadata:

  name: ml-model-champion

  namespace: ml-serving

  labels:

    app: ml-model

    version: champion

    model-version: v2.1

spec:

  replicas: 3

  selector:

    matchLabels:

      app: ml-model

      version: champion

  template:

    metadata:

      labels:

        app: ml-model

        version: champion

    spec:

      # Pod Scheduling — GPU Node Affinity

      affinity:

        nodeAffinity:

          requiredDuringSchedulingIgnoredDuringExecution:

            nodeSelectorTerms:

              - matchExpressions:

                  - key: nvidia.com/gpu.product

                    operator: In

                    values: ["Tesla-T4", "A10G"]

        # Pod Anti-affinity — กระจาย Pod ไปคนละ Node

        podAntiAffinity:

          preferredDuringSchedulingIgnoredDuringExecution:

            - weight: 100

              podAffinityTerm:

                labelSelector:

                  matchExpressions:

                    - key: app

                      operator: In

                      values: ["ml-model"]

                topologyKey: kubernetes.io/hostname

      # Tolerations สำหรับ GPU Nodes

      tolerations:

        - key: nvidia.com/gpu

          operator: Exists

          effect: NoSchedule

      # Topology Spread — กระจายข้าม AZ

      topologySpreadConstraints:

        - maxSkew: 1

          topologyKey: topology.kubernetes.io/zone

          whenUnsatisfiable: DoNotSchedule

          labelSelector:

            matchLabels:

              app: ml-model

      containers:

        - name: model-server

          image: registry/ml-model:v2.1-champion

          ports:

            - containerPort: 8080

          resources:

            requests:

              cpu: "2"

              memory: 4Gi

              nvidia.com/gpu: "1"

            limits:

              cpu: "4"

              memory: 8Gi

              nvidia.com/gpu: "1"

          env:

            - name: MODEL_VERSION

              value: "champion-v2.1"

            - name: AB_TEST_GROUP

              value: "control"

          readinessProbe:

            httpGet:

              path: /health

              port: 8080

            initialDelaySeconds: 30

            periodSeconds: 10

          livenessProbe:

            httpGet:

              path: /health

              port: 8080

            initialDelaySeconds: 60

            periodSeconds: 15

---

# === Challenger Model Deployment ===

apiVersion: apps/v1

kind: Deployment

metadata:

  name: ml-model-challenger

  namespace: ml-serving

  labels:

    app: ml-model

    version: challenger

    model-version: v3.0-beta

spec:

  replicas: 1

  selector:

    matchLabels:

      app: ml-model

      version: challenger

  template:

    metadata:

      labels:

        app: ml-model

        version: challenger

    spec:

      affinity:

        nodeAffinity:

          requiredDuringSchedulingIgnoredDuringExecution:

            nodeSelectorTerms:

              - matchExpressions:

                  - key: nvidia.com/gpu.product

                    operator: In

                    values: ["Tesla-T4", "A10G"]

      tolerations:

        - key: nvidia.com/gpu

          operator: Exists

          effect: NoSchedule

      containers:

        - name: model-server

          image: registry/ml-model:v3.0-challenger

          ports:

            - containerPort: 8080

          resources:

            requests:

              cpu: "2"

              memory: 4Gi

              nvidia.com/gpu: "1"

            limits:

              cpu: "4"

              memory: 8Gi

              nvidia.com/gpu: "1"

          env:

            - name: MODEL_VERSION

              value: "challenger-v3.0"

            - name: AB_TEST_GROUP

              value: "treatment"
Python — A/B Test Statistical Analysis
# ab_test_analyzer.py — วิเคราะห์ผล A/B Testing สำหรับ ML Models

import numpy as np

from scipy import stats

from dataclasses import dataclass

from typing import Optional

import json


@dataclass

class ABTestResult:

    test_name: str

    champion_metric: float

    challenger_metric: float

    p_value: float

    significant: bool

    winner: str

    confidence_interval: tuple

    sample_size_champion: int

    sample_size_challenger: int

    effect_size: float


class MLABTestAnalyzer:

    """วิเคราะห์ A/B Testing สำหรับ ML Models"""


    def __init__(self, alpha=0.05, power=0.8):

        self.alpha = alpha

        self.power = power


    def calculate_sample_size(self, baseline_rate, mde, alpha=None,

                              power=None):

        """คำนวณ Sample Size ที่ต้องการ"""

        alpha = alpha or self.alpha

        power = power or self.power


        z_alpha = stats.norm.ppf(1 - alpha / 2)

        z_power = stats.norm.ppf(power)

        p1 = baseline_rate

        p2 = baseline_rate + mde


        n = ((z_alpha * np.sqrt(2 * p1 * (1 - p1)) +

              z_power * np.sqrt(p1 * (1 - p1) + p2 * (1 - p2))) /

             mde) ** 2


        return int(np.ceil(n))


    def test_conversion(self, champion_conversions, champion_total,

                        challenger_conversions, challenger_total):

        """Chi-squared Test สำหรับ Conversion Rate"""

        champion_rate = champion_conversions / champion_total

        challenger_rate = challenger_conversions / challenger_total


        contingency = np.array([

            [champion_conversions, champion_total - champion_conversions],

            [challenger_conversions, challenger_total - challenger_conversions],

        ])


        chi2, p_value, _, _ = stats.chi2_contingency(contingency)


        # Effect Size (Cohen's h)

        h1 = 2 * np.arcsin(np.sqrt(champion_rate))

        h2 = 2 * np.arcsin(np.sqrt(challenger_rate))

        effect_size = abs(h2 - h1)


        # Confidence Interval for difference

        diff = challenger_rate - champion_rate

        se = np.sqrt(champion_rate * (1 - champion_rate) / champion_total +

                     challenger_rate * (1 - challenger_rate) / challenger_total)

        ci = (diff - 1.96 * se, diff + 1.96 * se)


        winner = "challenger" if challenger_rate > champion_rate and \

                 p_value < self.alpha else "champion"


        return ABTestResult(

            test_name="Conversion Rate",

            champion_metric=champion_rate,

            challenger_metric=challenger_rate,

            p_value=p_value,

            significant=p_value < self.alpha,

            winner=winner,

            confidence_interval=ci,

            sample_size_champion=champion_total,

            sample_size_challenger=challenger_total,

            effect_size=effect_size,

        )


    def test_continuous(self, champion_values, challenger_values,

                        metric_name="Latency"):

        """T-test สำหรับ Continuous Metrics (เช่น Latency)"""

        t_stat, p_value = stats.ttest_ind(champion_values,

                                           challenger_values)


        champion_mean = np.mean(champion_values)

        challenger_mean = np.mean(challenger_values)


        # Cohen's d

        pooled_std = np.sqrt(

            (np.std(champion_values)**2 + np.std(challenger_values)**2) / 2

        )

        effect_size = abs(champion_mean - challenger_mean) / pooled_std


        # CI for difference

        diff = challenger_mean - champion_mean

        se = np.sqrt(np.var(champion_values) / len(champion_values) +

                     np.var(challenger_values) / len(challenger_values))

        ci = (diff - 1.96 * se, diff + 1.96 * se)


        # สำหรับ Latency ต่ำกว่าดีกว่า

        if "latency" in metric_name.lower():

            winner = "challenger" if challenger_mean < champion_mean and \

                     p_value < self.alpha else "champion"

        else:

            winner = "challenger" if challenger_mean > champion_mean and \

                     p_value < self.alpha else "champion"


        return ABTestResult(

            test_name=metric_name,

            champion_metric=champion_mean,

            challenger_metric=challenger_mean,

            p_value=p_value,

            significant=p_value < self.alpha,

            winner=winner,

            confidence_interval=ci,

            sample_size_champion=len(champion_values),

            sample_size_challenger=len(challenger_values),

            effect_size=effect_size,

        )


    def print_report(self, results: list[ABTestResult]):

        """แสดงรายงาน A/B Test"""

        print("=" * 60)

        print("A/B Test Report — ML Model Comparison")

        print("=" * 60)


        for r in results:

            sig = "YES" if r.significant else "NO"

            print(f"\n--- {r.test_name} ---")

            print(f"  Champion:   {r.champion_metric:.4f} "

                  f"(n={r.sample_size_champion})")

            print(f"  Challenger: {r.challenger_metric:.4f} "

                  f"(n={r.sample_size_challenger})")

            print(f"  p-value:    {r.p_value:.4f}")

            print(f"  Significant: {sig} (alpha={self.alpha})")

            print(f"  Effect Size: {r.effect_size:.3f}")

            print(f"  95% CI:     ({r.confidence_interval[0]:.4f}, "

                  f"{r.confidence_interval[1]:.4f})")

            print(f"  Winner:     {r.winner.upper()}")


# ตัวอย่าง

analyzer = MLABTestAnalyzer(alpha=0.05)


# Sample Size Calculation

n = analyzer.calculate_sample_size(baseline_rate=0.05, mde=0.01)

print(f"Required sample size per group: {n}")


# Conversion Test

conv = analyzer.test_conversion(

    champion_conversions=500, champion_total=10000,

    challenger_conversions=550, challenger_total=10000,

)


# Latency Test

np.random.seed(42)

champ_latency = np.random.normal(45, 10, 5000)

chall_latency = np.random.normal(42, 9, 5000)

lat = analyzer.test_continuous(champ_latency, chall_latency, "Latency (ms)")


analyzer.print_report([conv, lat])
Monitoring A/B Test ด้วย Prometheus
# === Prometheus Queries สำหรับ A/B Test Monitoring ===


# 1. Request Rate per Model Version

rate(ml_model_requests_total{namespace="ml-serving"}[5m])


# 2. Latency P99 per Model Version

histogram_quantile(0.99,

  rate(ml_model_latency_seconds_bucket{namespace="ml-serving"}[5m])

)


# 3. Error Rate per Model Version

sum(rate(ml_model_errors_total{namespace="ml-serving"}[5m])) by (version)

/

sum(rate(ml_model_requests_total{namespace="ml-serving"}[5m])) by (version)


# 4. GPU Utilization per Pod

avg(DCGM_FI_DEV_GPU_UTIL{namespace="ml-serving"}) by (pod)


# === Grafana Dashboard JSON (Panel) ===

# {

#   "title": "A/B Test — Model Comparison",

#   "panels": [

#     {

#       "title": "Request Rate by Version",

#       "targets": [{"expr": "rate(ml_requests_total[5m])"}],

#       "type": "timeseries"

#     },

#     {

#       "title": "P99 Latency by Version",

#       "targets": [{"expr": "histogram_quantile(0.99, rate(ml_latency_bucket[5m]))"}],

#       "type": "timeseries"

#     }

#   ]

# }


# === kubectl Commands สำหรับ Pod Scheduling ===


# ดู Pod Placement

kubectl get pods -n ml-serving -o wide \

  -l app=ml-model


# ดู Node Resources (GPU)

kubectl describe nodes | grep -A5 "Allocated resources"


# ดู GPU Utilization

kubectl top pods -n ml-serving --containers


# Scale Challenger ขึ้นเมื่อ A/B Test ผ่าน

kubectl scale deployment ml-model-challenger \

  -n ml-serving --replicas=3


# อัปเดต Traffic Weight (Istio)

kubectl patch virtualservice ml-model-ab-test \

  -n ml-serving --type merge \

  -p '{"spec":{"http":[{"route":[

    {"destination":{"host":"ml-model-champion"},"weight":50},

    {"destination":{"host":"ml-model-challenger"},"weight":50}

  ]}]}}'
Best Practices
- คำนวณ Sample Size ก่อน: กำหนด MDE (Minimum Detectable Effect) และคำนวณ Sample Size ที่ต้องการก่อนเริ่ม Test
- เริ่ม Traffic น้อย: เริ่มที่ 5-10% แล้วค่อยเพิ่ม ตรวจสอบ Error Rate ก่อน
- GPU Scheduling: ใช้ Node Affinity สำหรับ GPU Nodes, Topology Spread กระจายข้าม AZ
- อย่าดู Results เร็วเกินไป: รอจนได้ Sample Size เพียงพอ อย่าสรุปผลก่อนเวลา (Peeking Problem)
- Monitor ทุก Metric: ไม่ใช่แค่ Primary Metric ดู Latency, Error Rate, Resource Usage ด้วย
- Automated Rollback: ตั้ง Alert ถ้า Challenger มี Error Rate สูงกว่า Threshold ให้ Rollback อัตโนมัติ
A/B Testing สำหรับ ML Models คืออะไร
เปรียบเทียบ Model 2 ตัวขึ้นไปโดยส่ง Traffic จริงตามสัดส่วน วัดผลด้วย Metrics จริง เช่น Accuracy Latency Conversion Rate ตัดสินใจว่า Model ไหนดีกว่าก่อน Deploy เต็ม 100%